主管:中国科学院
主办:中国优选法统筹法与经济数学研究会
中国科学院科技战略咨询研究院
主办:中国优选法统筹法与经济数学研究会
中国科学院科技战略咨询研究院
Chinese Journal of Management Science ›› 2026, Vol. 34 ›› Issue (10): 107-117.doi: 10.16381/j.cnki.issn1003-207x.2023.1157
Qingyuan Zhu1,2, Shuqi Xu3( ), Yinghao Pan4, Jie Wu4
Received:2023-07-11
Revised:2024-03-26
Online:2026-10-25
Published:2026-10-09
Contact:
Shuqi Xu
E-mail:xusq@hfuu.edu.cn
CLC Number:
Qingyuan Zhu,Shuqi Xu,Yinghao Pan, et al. The Computation Acceleration of DEA in the Big Data Context[J]. Chinese Journal of Management Science, 2026, 34(10): 107-117.
"


"
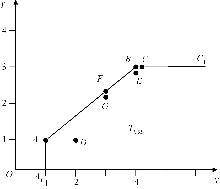
| DMU | 投入 | 产出 | 分值 |
|---|---|---|---|
| A | 1 | 1 | 142.86 |
| B | 4 | 3 | 128.57 |
| C | 4.1 | 3 | 128.57 |
| D | 2 | 1 | 114.29 |
| E | 4 | 2.9 | 114.29 |
| F | 3 | 7/3 | 114.29 |
| G | 3 | 2 | 114.29 |
"
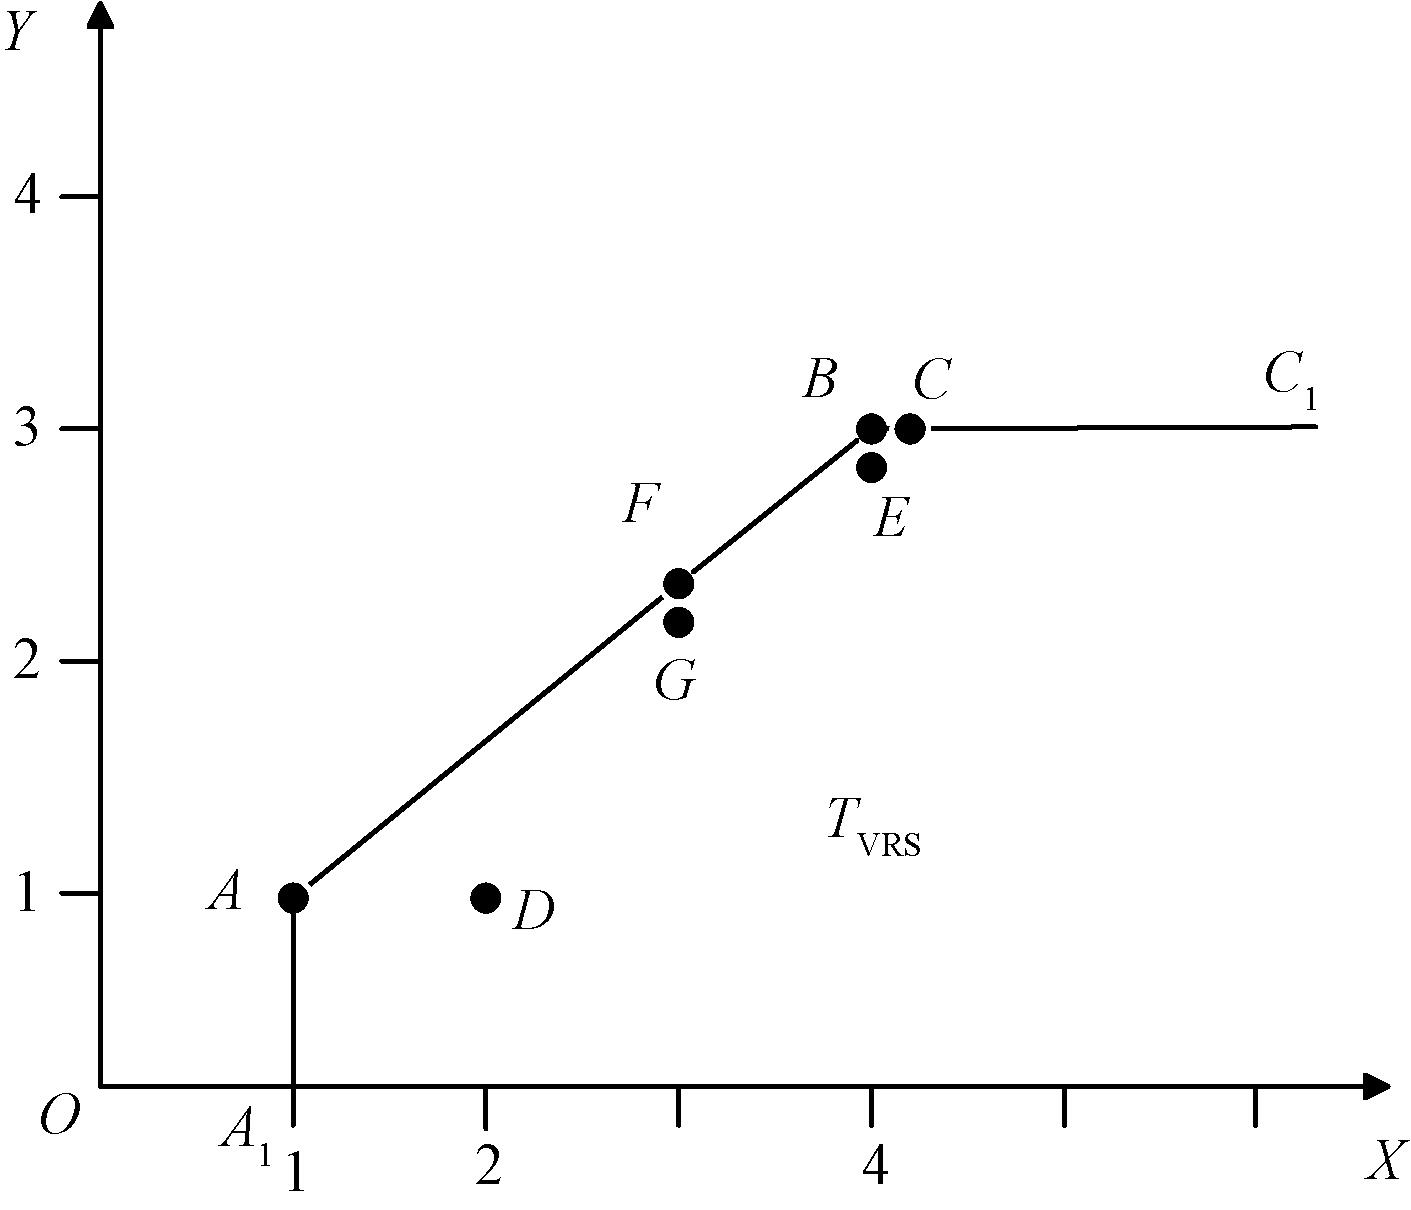
"
| DMU | 投入 | 产出 | 改进后有效度排序 |
|---|---|---|---|
| A | 1 | 1 | 1 |
| F | 3 | 7/3 | 2 |
| B | 4 | 3 | 3 |
| C | 4.1 | 3 | 4 |
| E | 4 | 2.9 | 5 |
| G | 3 | 2 | 6 |
| D | 2 | 1 | 7 |
"
| 数据 | 平均值 | 方差 | 最大值 | 最小值 |
|---|---|---|---|---|
| 营业总成本(元) | 115.83 | 708.37 | 28868.87 | 0.03 |
| 营业收入(元) | 126.98 | 762.23 | 29661.93 | 0.00 |
| 营业外收入(元) | 0.37 | 2.03 | 106.35 | 0.00 |
"
| DMU个数(有效单元个数) | 特殊分块法抓取有效单元数目 | 特殊分块法抓取时间 | 改进后抓取有效单元数目 | 改进后抓取时间 |
|---|---|---|---|---|
| 500 (31) | 26 | 0.03 | 27 | 0.03 |
| 1000 (62) | 45 | 0.06 | 51 | 0.06 |
| 2000 (114) | 75 | 0.16 | 90 | 0.15 |
| 5000 (266) | 130 | 0.88 | 142 | 0.86 |
"
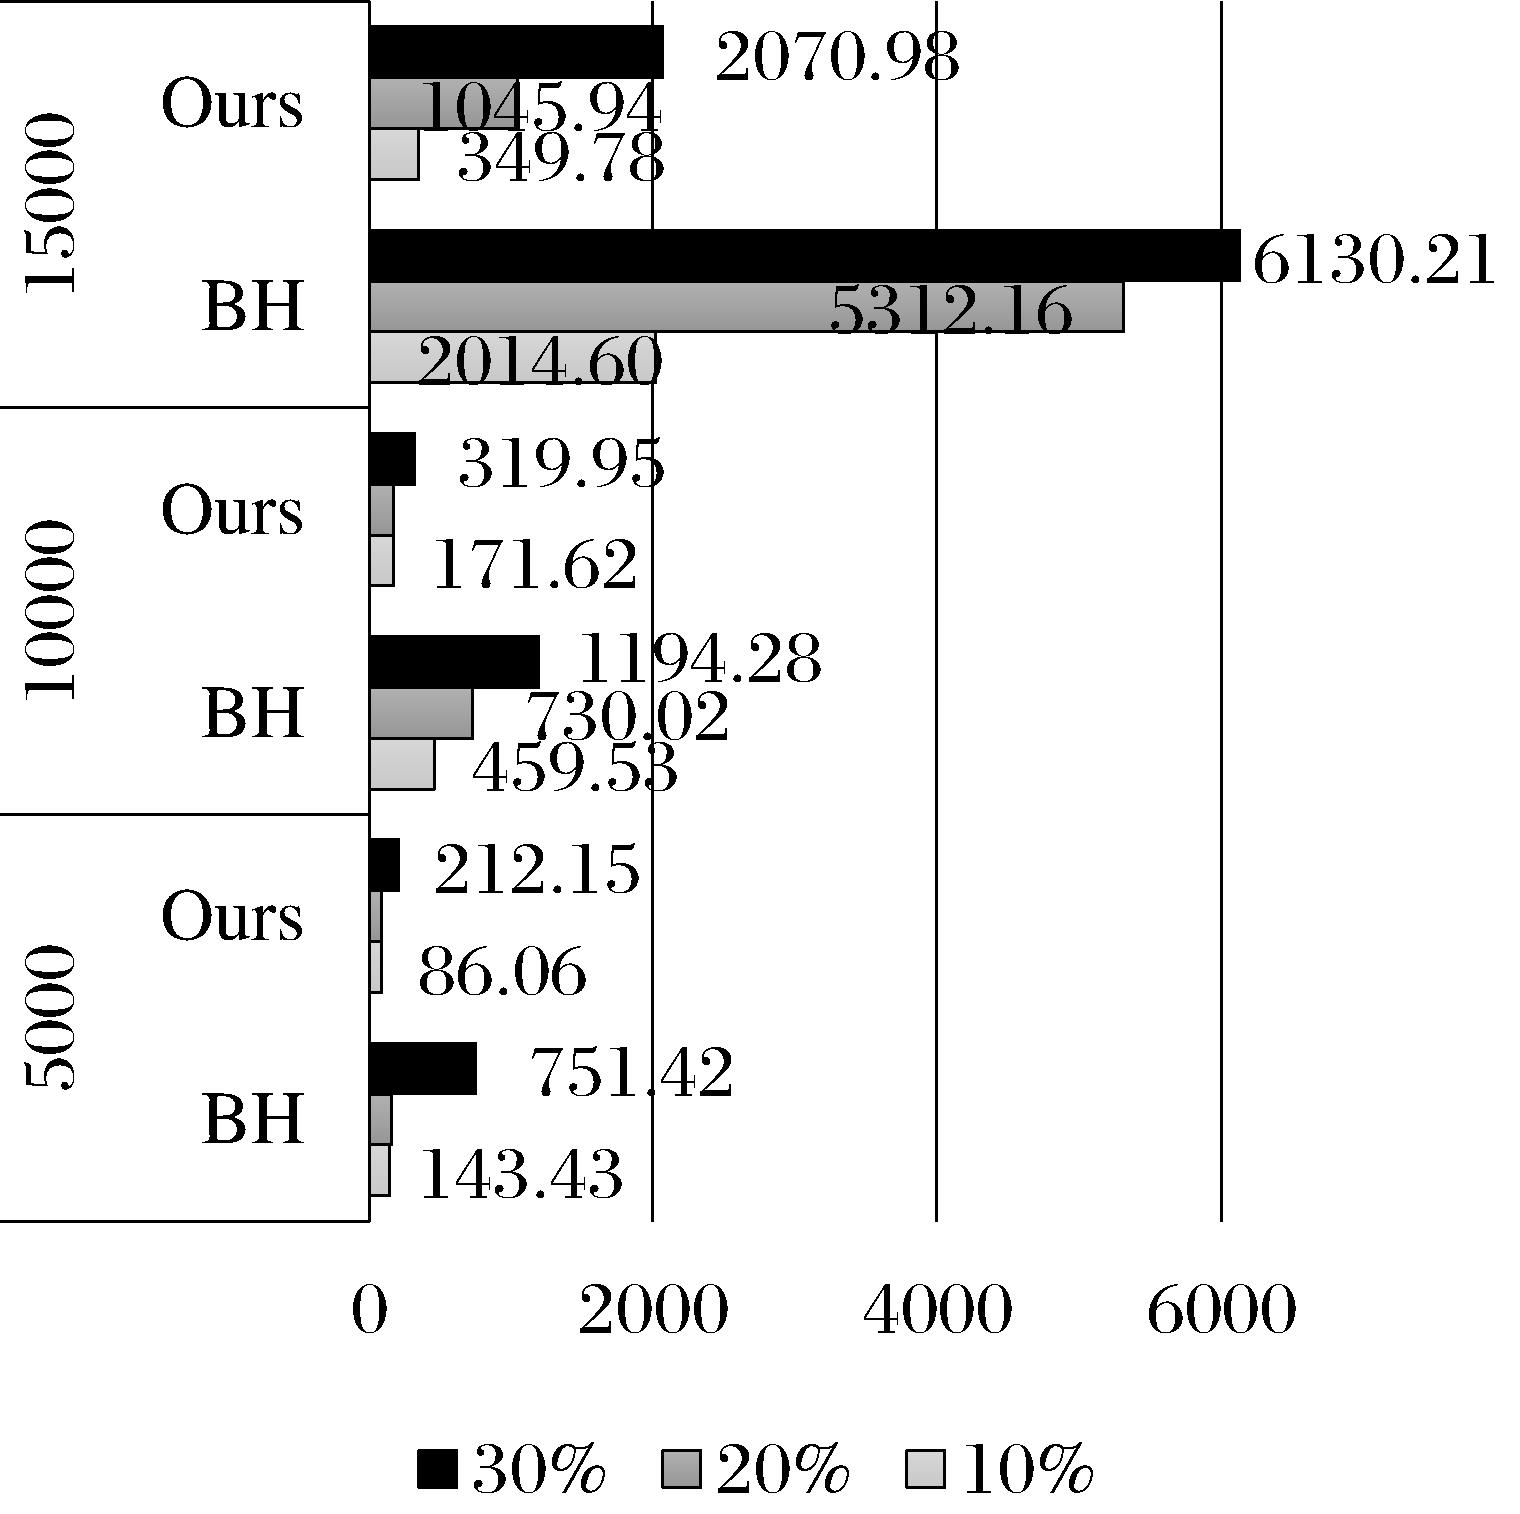
| 传统方法运行时间(秒) | 本文方法运行时间(秒) | 清洗样本所用时间(秒) | 清洗样本量(个) |
|---|---|---|---|
| 36866.30 | 361.98 | 186.64 | 22857 |
"
| 1 | 0.8 ~ 1 | 0.6 ~ 0.8 | 0.4 ~ 0.6 | 0.2 ~ 0.4 | 0 ~ 0.2 |
|---|---|---|---|---|---|
| 2 | 0 | 2 | 1 | 5 | 22922 |
"
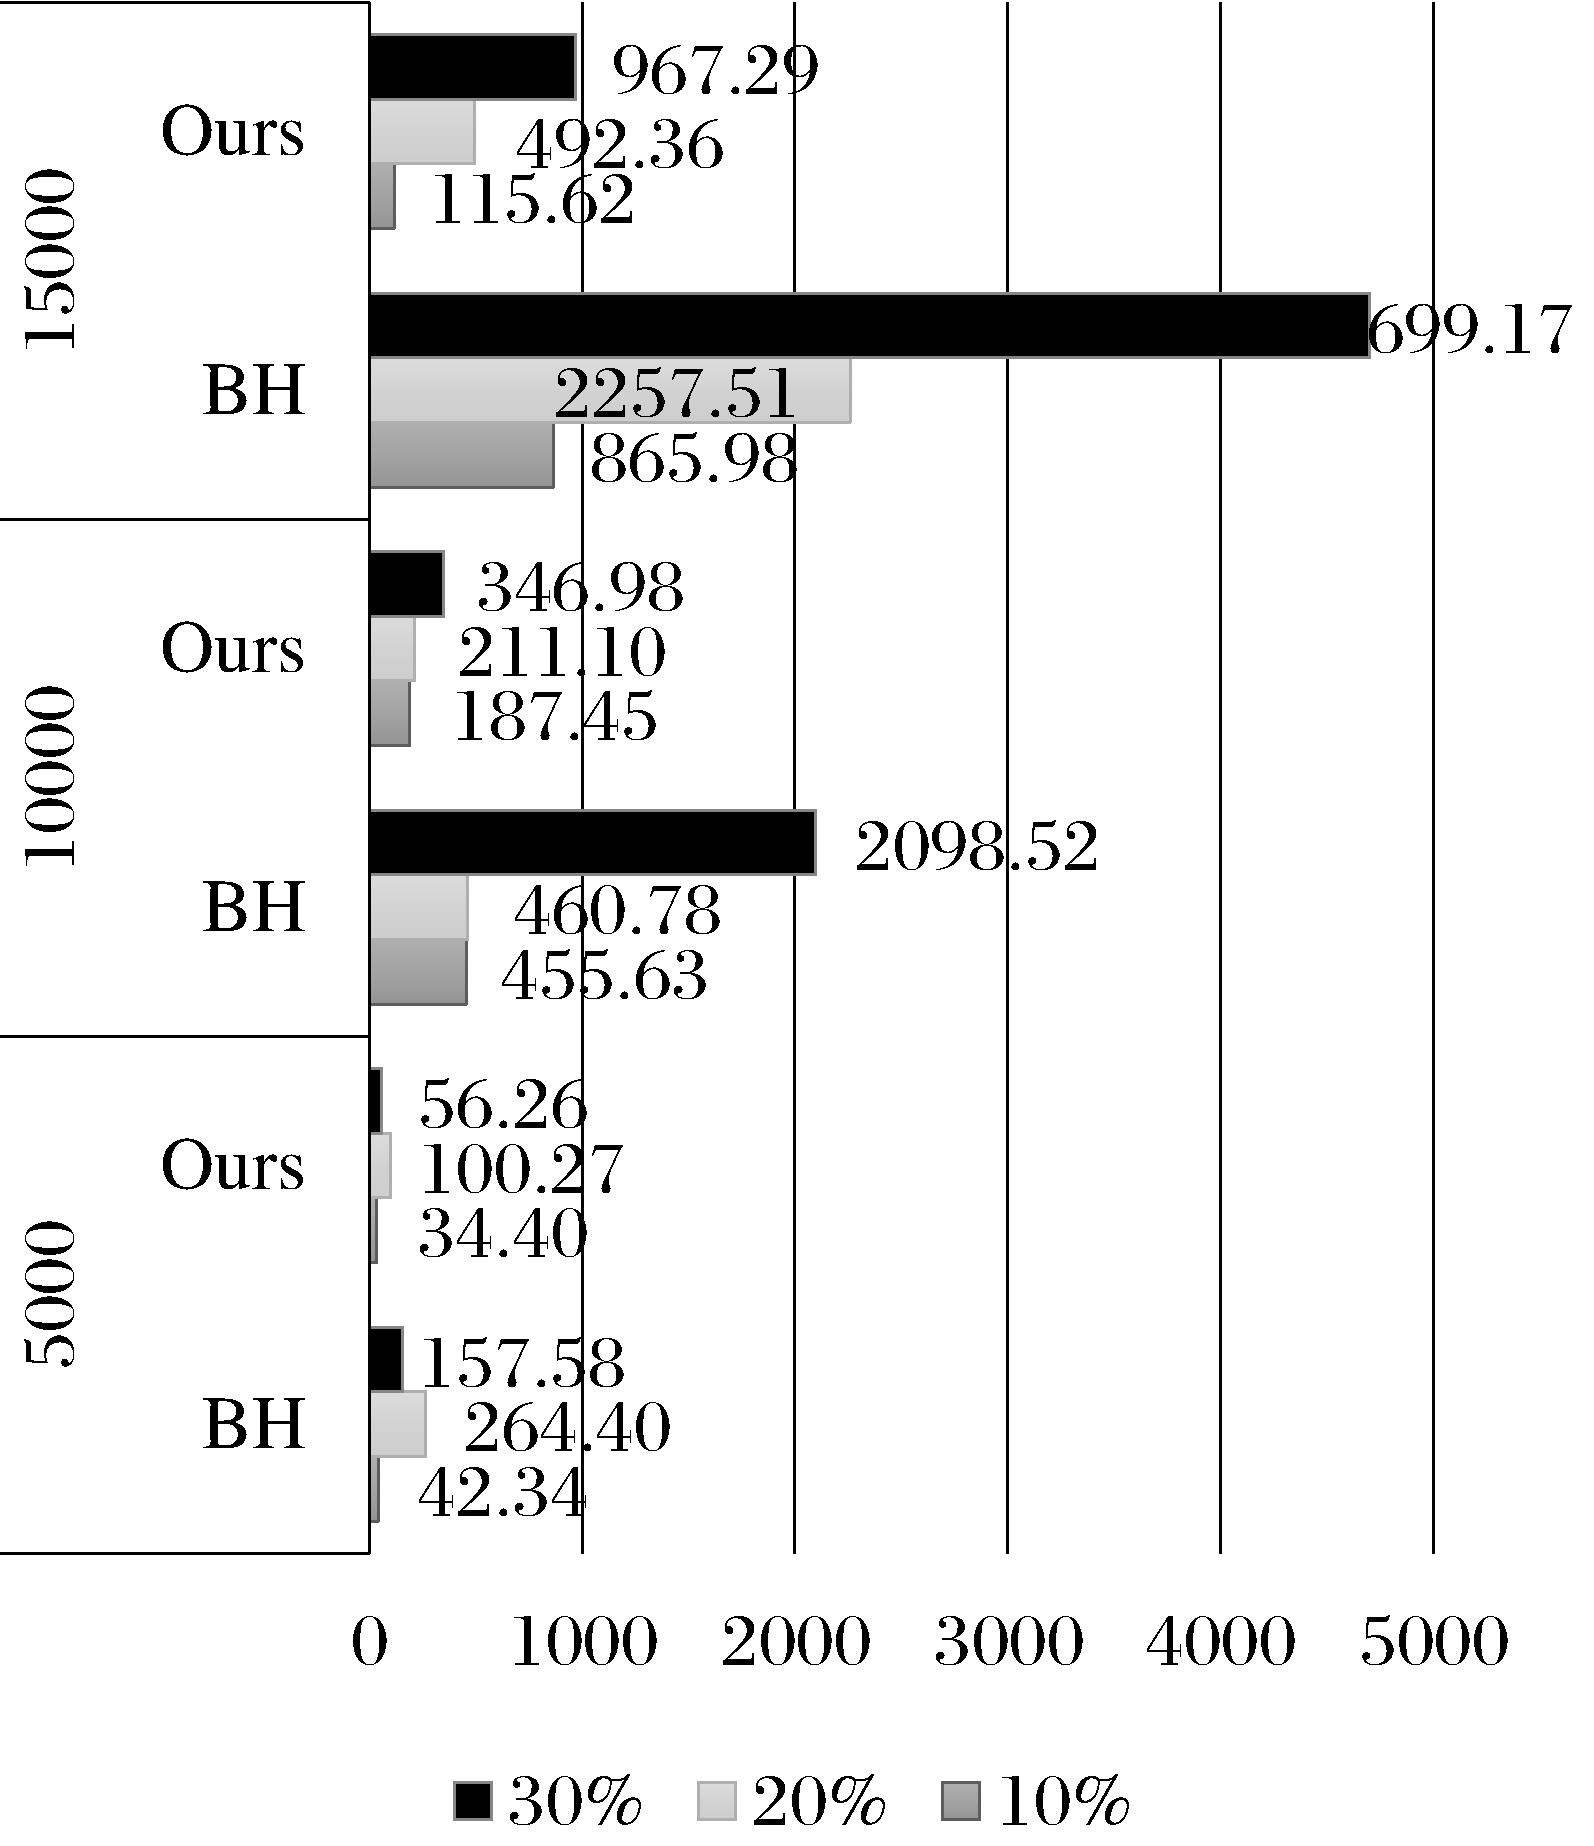
"
| [1] | 李国杰, 程学旗. 大数据研究: 未来科技及经济社会发展的重大战略领域——大数据的研究现状与科学思考[J]. 中国科学院院刊, 2012, 27(6): 647-657. |
| Li G J, Cheng X Q. Research status and scientific thinking of big data[J]. Bulletin of the Chinese Academy of Sciences, 2012, 27(6): 647-657. | |
| [2] | Adams J U. Genetics: Big hopes for big data[J]. Nature, 2015, 527(7578): S108-S109. |
| [3] | Einav L, Levin J. Economics in the age of big data[J]. Science, 2014, 346(6210): 1243089. |
| [4] | Frégnac Y. Big data and the industrialization of neuroscience: A safe roadmap for understanding the brain?[J]. Science, 2017, 358(6362): 470-477. |
| [5] | Sagiroglu S, Sinanc D. Big data: A review[C]//Proceedings of 2013 International Conference on Collaboration Technologies and Systems (CTS), San Diego, CA, USA, May 20-24, IEEE, 2013: 42-47. |
| [6] | 陈国青, 吴刚, 顾远东, 等. 管理决策情境下大数据驱动的研究和应用挑战——范式转变与研究方向[J]. 管理科学学报, 2018, 21(7): 1-10. |
| Chen G Q, Wu G, Gu Y D, et al. The challenges for big data driven research and applications in the context of managerial decision-making: Paradigm shift and research directions[J]. Journal of Management Sciences in China, 2018, 21(7): 1-10. | |
| [7] | Charnes A, Cooper W W, Rhodes E. Measuring the efficiency of decision making units[J]. European Journal of Operational Research, 1978, 2(6): 429-444. |
| [8] | Banker R D, Charnes A, Cooper W W. Some models for estimating technical and scale inefficiencies in data envelopment analysis[J]. Management Science, 1984, 30(9): 1078-1092. |
| [9] | Seiford L M, Zhu J. Profitability and marketability of the top 55 U.S. commercial banks[J]. Management Science, 1999, 45(9): 1270-1288. |
| [10] | Podinovski V V. Variable and constant returns-to-scale production technologies with component processes[J]. Operations Research, 2022, 70(2): 1238-1258. |
| [11] | Sueyoshi T. Measuring efficiencies and returns to scale of Nippon telegraph & telephone in production and cost analyses[J]. Management Science, 1997, 43(6): 779-796. |
| [12] | Staub R B, da Silva e Souza G, Tabak B M. Evolution of bank efficiency in Brazil: A DEA approach[J]. European Journal of Operational Research, 2010, 202(1): 204-213. |
| [13] | Sueyoshi T, Goto M. Weak and strong disposability vs. Natural and managerial disposability in DEA environmental assessment: Comparison between Japanese electric power industry and manufacturing industries[J]. Energy Economics, 2012, 34(3): 686-699. |
| [14] | Mao W, Koo W W. Productivity growth, technological progress, and efficiency change in Chinese agriculture after rural economic reforms: A DEA approach[J]. China Economic Review, 1997, 8(2): 157-174. |
| [15] | O’Neill L, Rauner M, Heidenberger K, et al. A cross-national comparison and taxonomy of DEA-based hospital efficiency studies[J]. Socio-Economic Planning Sciences, 2008, 42(3): 158-189. |
| [16] | Wu J, Zhu Q, Chu J, et al. Measuring energy and environmental efficiency of transportation systems in China based on a parallel DEA approach[J]. Transportation Research Part D: Transport and Environment, 2016, 48: 460-472. |
| [17] | Sinuany-Stern Z. Foundations of operations research: From linear programming to data envelopment analysis[J]. European Journal of Operational Research, 2023, 306(3): 1069-1080. |
| [18] | Dulá J H. Data envelopment analysis (DEA): Algorithms, computations, and Geometry[M]// Charles V, Aparicio J, Zhu J. Data Science and Productivity Analytics. Cham: Springer, 2020: 35-56. |
| [19] | Farrell M J. The measurement of productive efficiency[J]. Journal of the Royal Statistical Society Series A (General), 1957, 120(3): 253-290. |
| [20] | Cook W D, Seiford L M. Data envelopment analysis (DEA)–Thirty years on[J]. European Journal of Operational Research, 2009, 192(1): 1-17. |
| [21] | Tone K. A slacks-based measure of efficiency in data envelopment analysis[J]. European Journal of Operational Research, 2001, 130(3): 498-509. |
| [22] | Wei Q, Zhang J, Zhang X. An inverse DEA model for inputs/outputs estimate[J]. European Journal of Operational Research, 2000, 121(1): 151-163. |
| [23] | Kerstens K, Van de Woestyne I. Negative data in DEA: A simple proportional distance function approach[J]. Journal of the Operational Research Society, 2011, 62(7): 1413-1419. |
| [24] | Kuosmanen T, Matin R K. Theory of integer-valued data envelopment analysis[J]. European Journal of Operational Research, 2009, 192(2): 658-667. |
| [25] | 陈金晓, 陈剑. 考虑断链风险的供应链绩效测度与Nash谈判[J]. 管理科学学报, 2023, 26(1): 1-18. |
| Chen J X, Chen J. Supply chain performance measurement and Nash bargaining considering the risk of chain break[J]. Journal of Management Sciences in China, 2023, 26(1): 1-18. | |
| [26] | Adler N, Olesen O B, Volta N. Identifying merger opportunities: The case of air traffic control[J]. Operations Research, 2024, 72(1): 389-409. |
| [27] | Olesen O B, Petersen N C. Indicators of ill-conditioned data sets and model misspecification in data envelopment analysis: An extended facet approach[J]. Management Science, 1996, 42(2): 205-219. |
| [28] | Dakpo K H, Jeanneaux P, Latruffe L. Modelling pollution-generating technologies in performance benchmarking: Recent developments, limits and future prospects in the nonparametric framework[J]. European Journal of Operational Research, 2016, 250(2): 347-359. |
| [29] | Chen Y, Cook W D, Kao C, et al. Network DEA pitfalls: Divisional efficiency and frontier projection[M]//Cook W D,Zhu J. Data Envelopment Analysis: A Handbook on the Modeling of Internal Structures and Networks. Boston, MA: Springer, 2014: 31-54. |
| [30] | 孟小峰, 慈祥. 大数据管理: 概念、技术与挑战[J]. 计算机研究与发展, 2013, 50(1): 146-169. |
| Meng X F, Ci X. Big data management: Concepts, techniques and challenges[J]. Journal of Computer Research and Development, 2013, 50(1): 146-169. | |
| [31] | Sueyoshi T, Chang Y L. Efficient algorithm for additive and multiplicative models in data envelopment analysis[J]. Operations Research Letters, 1989, 8(4): 205-213. |
| [32] | Ali A I. Streamlined computation for data envelopment analysis[J]. European Journal of Operational Research, 1993, 64(1): 61-67. |
| [33] | Dulá J H, López F J. Preprocessing DEA[J]. Computers & Operations Research, 2009, 36(4): 1204-1220. |
| [34] | Dulá J H. A computational study of DEA with massive data sets[J]. Computers & Operations Research, 2008, 35(4): 1191-1203. |
| [35] | Barr R S, Durchholz M L. Parallel and hierarchical decomposition approaches for solving large-scale Data Envelopment Analysis models[J]. Annals of Operations Research, 1997, 73: 339-372. |
| [36] | Zhu Q, Wu J, Song M. Efficiency evaluation based on data envelopment analysis in the big data context[J]. Computers & Operations Research, 2018, 98: 291-300. |
| [37] | Dellnitz A. Big data efficiency analysis: Improved algorithms for data envelopment analysis involving large datasets[J]. Computers & Operations Research, 2022, 137: 105553. |
| [38] | Korhonen P J, Siitari P A. A dimensional decomposition approach to identifying efficient units in large-scale DEA models[J]. Computers & Operations Research, 2009, 36(1): 234-244. |
| [39] | Dulá J H. An algorithm for data envelopment analysis[J]. INFORMS Journal on Computing, 2011, 23(2): 284-296. |
| [40] | Jie T. Parallel processing of the Build Hull algorithm to address the large-scale DEA problem[J]. Annals of Operations Research, 2020, 295(1): 453-481. |
| [41] | Chen W C, Lai S Y. Determining radial efficiency with a large data set by solving small-size linear programs[J]. Annals of Operations Research, 2017, 250(1): 147-166. |
| [42] | Khezrimotlagh D, Zhu J, Cook W D, et al. Data envelopment analysis and big data[J]. European Journal of Operational Research, 2019, 274(3): 1047-1054. |
| [43] | Khezrimotlagh D, Zhu J. Data envelopment analysis and big data: Revisit with a faster method[M]//Charles V, Aparicio J, Zhu J.Data Science and Productivity Analytics. Cham: Springer, 2020: 1-34. |
| [44] | Zhou Y, Wang S, Xu S, et al. Big data in data envelopment analysis with undesirable outputs based on simulation and environmental-health matching data of Chinese industrial enterprises[J]. Annals of Operations Research, 2025, 348(1): 279-298. |
| [45] | Cobb C W, Douglas P H. A theory of production[J]. The American Economic Review,1928,18(1): 139-165. |
| [46] | Khezrimotlagh D. Simulation designs for production frontiers[J].European Journal of Operational Research, 2022, 303(3): 1321-1334. |
| [1] | Zeshui Xu, Mei Chang, Xunjie Gou. An Analysis of Inter-provincial Carbon Emission Efficiency and Its Influencing Factors in China: A Multi-period Cross-efficiency Approach [J]. Chinese Journal of Management Science, 2026, 34(6): 356-368. |
| [2] | Zhanxin Ma, Pengbo Hou. Meaning of Super-efficiency, Projection Reliability, and Robust Production Frontiers [J]. Chinese Journal of Management Science, 2026, 34(3): 146-158. |
| [3] | Jiang Li, Hecheng Wu, Liwen Wang. A Robust Data Envelopment Analysis Model with Common Weights Considering Uncertainty and Its Application [J]. Chinese Journal of Management Science, 2026, 34(3): 333-344. |
| [4] | Lei Chen, Xu Guo, Yingming Wang. Determination of Optimal Endogenous Direction and Improvement Path in Directional Distance Function [J]. Chinese Journal of Management Science, 2025, 33(9): 89-96. |
| [5] | Shuya Yan, Guotao Yang, Xun Liang, Zhenyu Guan, Ziyan Liu. Comprehensive Efficiency Evaluation of China’s Economic Development Quality Based on Parallel Two-stage Network DEA Model [J]. Chinese Journal of Management Science, 2025, 33(7): 139-150. |
| [6] | Ren Mu, Lining Hao, Ankang Li, Shuyi Zhang, Wei Cui. Group Ranking Data Envelopment Analysis Model [J]. Chinese Journal of Management Science, 2025, 33(7): 24-32. |
| [7] | Suoyi Tan, Mengning Wang, Ye Tian, Jianguo Liu, Xin Lu. Data-Driven Models and Applications on Poverty Identification, Classification, and Prediction [J]. Chinese Journal of Management Science, 2025, 33(5): 124-137. |
| [8] | Zhanxin Ma, guga Suri. Study of DEA-Malmquist Index Method Based on Frontier Surface Modification [J]. Chinese Journal of Management Science, 2025, 33(3): 118-127. |
| [9] | Yao Wen, Qingxian An, Yongli Li. Cost DEA Game and Cost Allocation Method Considering the Relative Competitiveness of Decision-making Units [J]. Chinese Journal of Management Science, 2025, 33(2): 71-83. |
| [10] | Haiyan Wang, Zhaohan Sheng. Modeling of Complex System Management Scenarios Driven by Big Data: Techniques and Processes [J]. Chinese Journal of Management Science, 2025, 33(1): 22-33. |
| [11] | Guangyu Wan,Feiyan Pu,Zichun Li,Yu Cao. Impact of Marketing Capability and Production Operation Capability on Firms' Financial Performance [J]. Chinese Journal of Management Science, 2024, 32(5): 275-285. |
| [12] | Xiuli Meng,Jing Yang,Bo Liu. Competition Strategy of Crowdsourcing Logistics Service Quality Based on Big Data Technology [J]. Chinese Journal of Management Science, 2024, 32(4): 130-140. |
| [13] | YAN Yu-meng, XIONG Xiong, LU Lei, ZHANG Wei, ZHANG Yong-jie. From “A Peek” to “A Strategic View”: Individual Investor Behaviors in the Age of Big Data [J]. Chinese Journal of Management Science, 2023, 31(9): 244-254. |
| [14] | ZHAO Hui, ZHANG Tao, TANG Ke. How does Agglomeration Affect Entrepreneurial Activities in the North and South? Evidence from High Frequency Full Enterprise Big Data [J]. Chinese Journal of Management Science, 2023, 31(6): 231-240. |
| [15] | ZHOU Zhen, JIAN Hong-yu, HUANG Jia-pei, LIN Yun. The Influence of E-marketing on Cinema Performance Based on DEA and Grey Entropy [J]. Chinese Journal of Management Science, 2023, 31(5): 240-248. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||
|
||
